Final Selected Model
Gradient Boosting · 50 estimators · maxDepth=3 · lr=0.1
Chosen for the best F1 / AUC balance without severe overfitting. Trained on a 5,000-row stratified subsample of the original imbalanced training data.
Gradient Boosting sequentially corrects previous errors and typically produces the best AUC on tabular data with mixed feature types. Shallow trees (depth=3) with a small learning rate (0.1) trade some training-set accuracy for better generalization.
We chose original (non-resampled) training data because the base rate (33% Denied) is not extreme enough to require SMOTE-like intervention, and resampling here traded precision for marginal recall gains without improving F1 (see Resampling page).
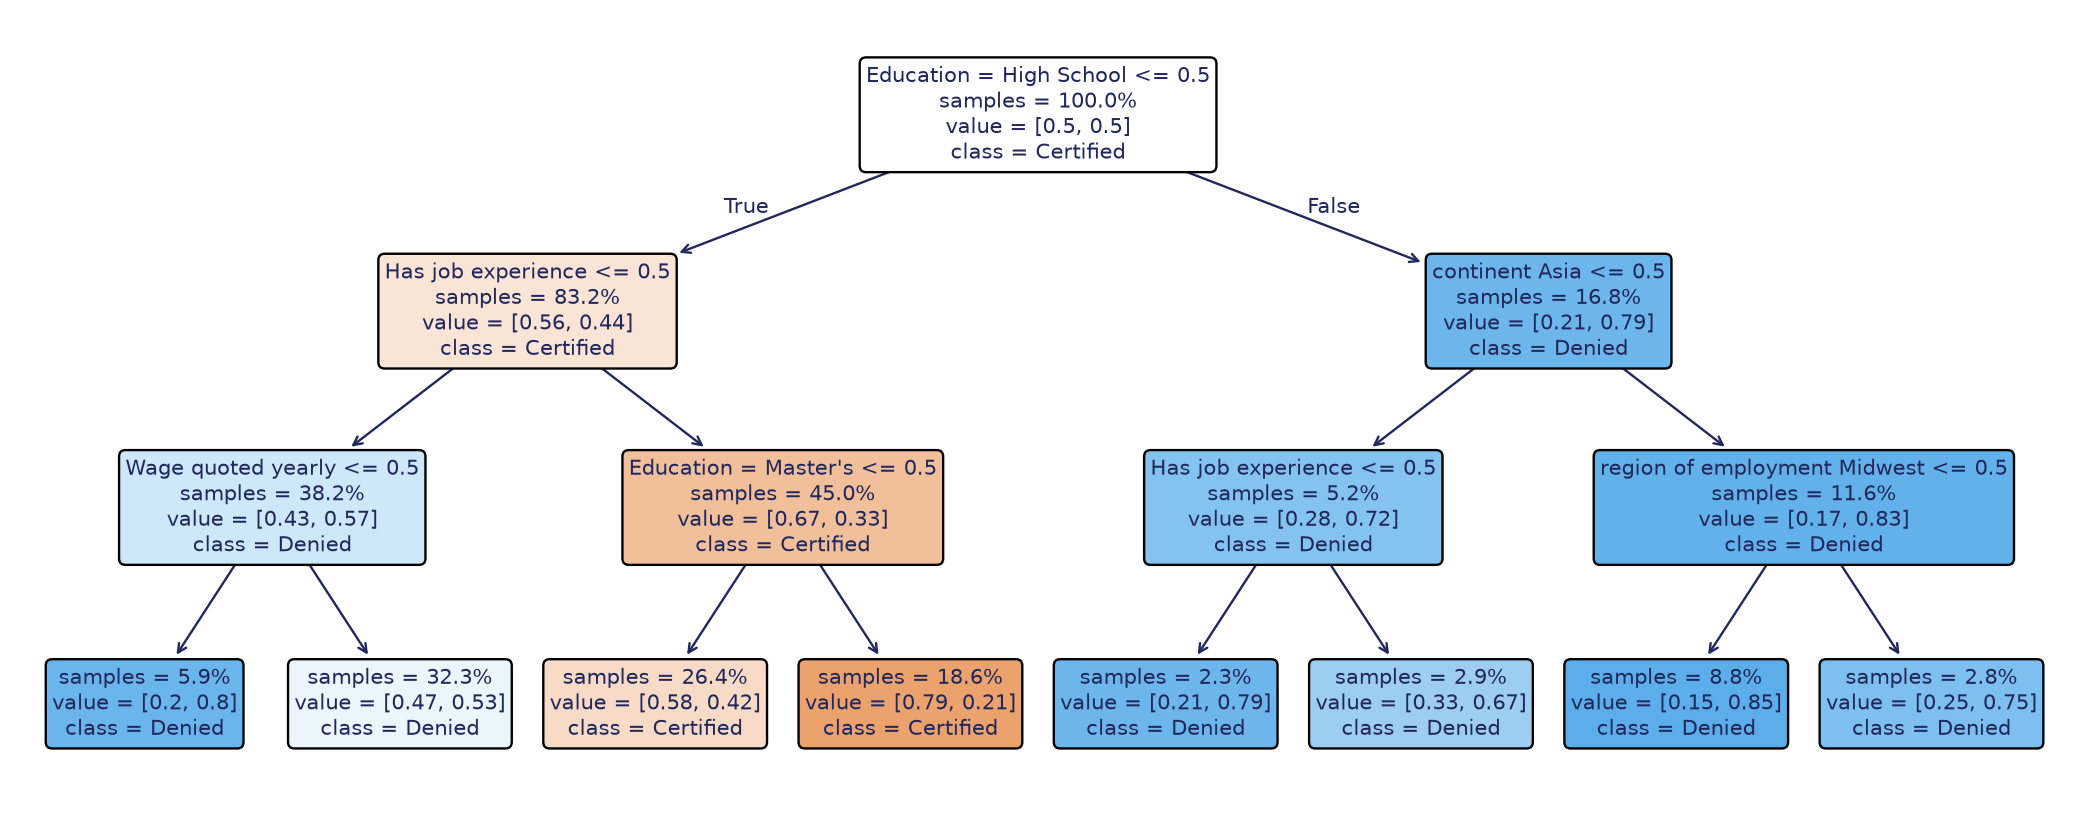
A readable stand-in for the ensemble: the first split is education (High School vs everything else), then prior job experience and continent — mirroring the importance ranking above. On held-out cases the surrogate reaches 57.44% F1 and 71.76% recall, so it is a faithful approximation of the deployed model rather than a separate story.